Data Science Beyond Model Accuracy: How to Build Reliable Solutions for Real-World Problems
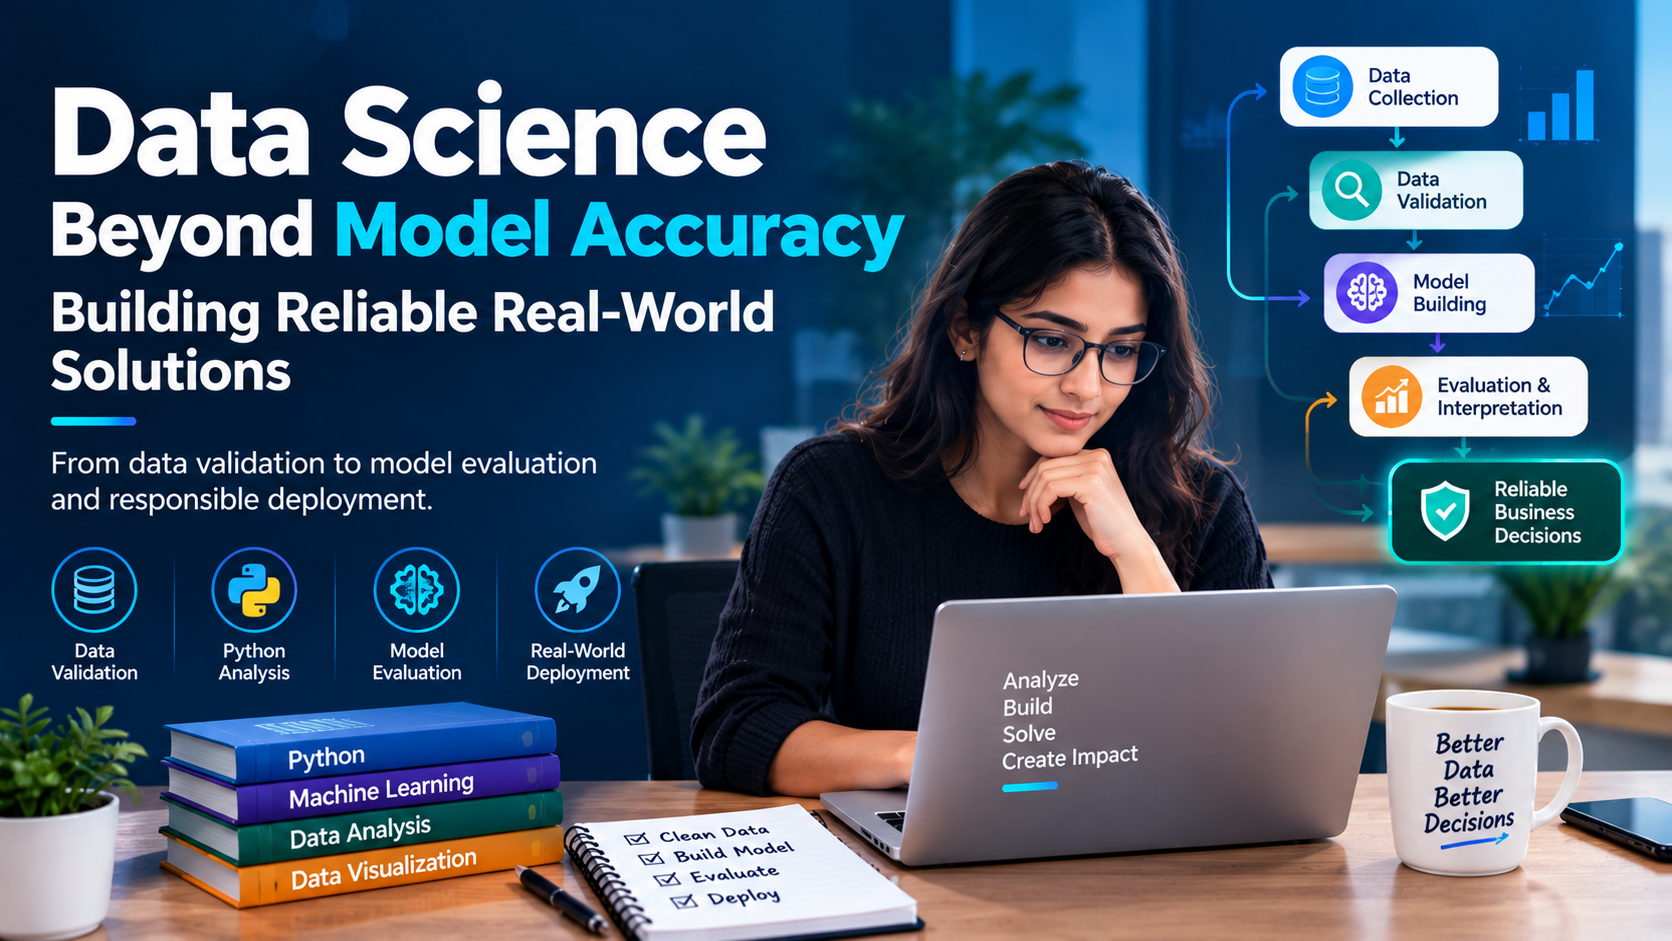
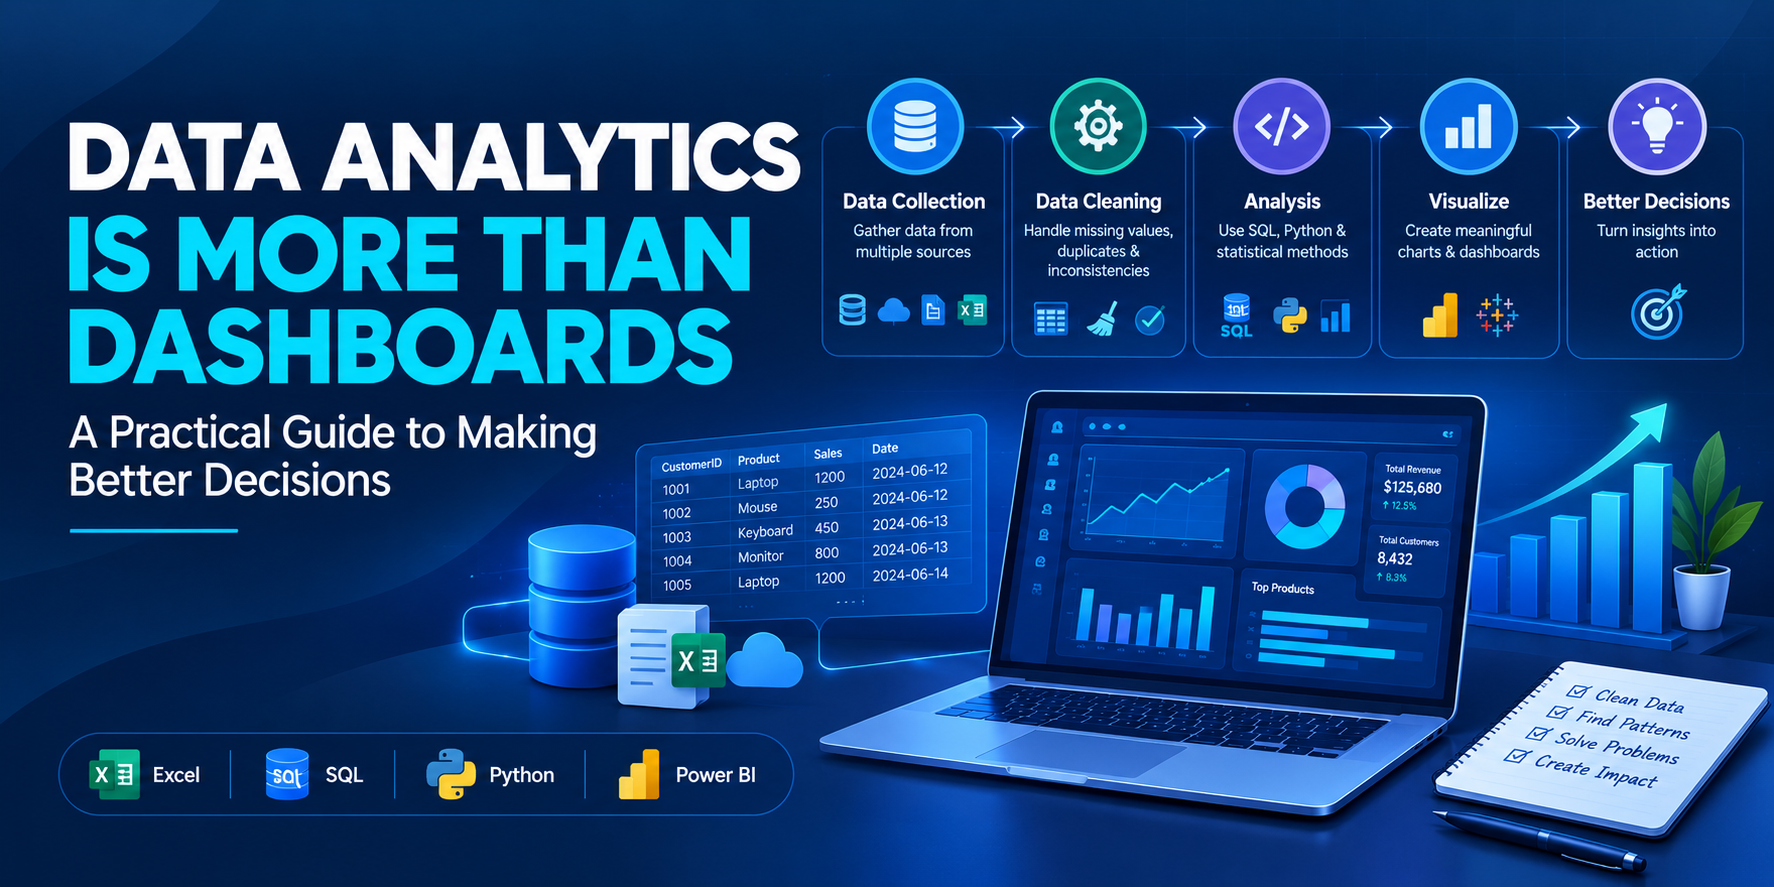
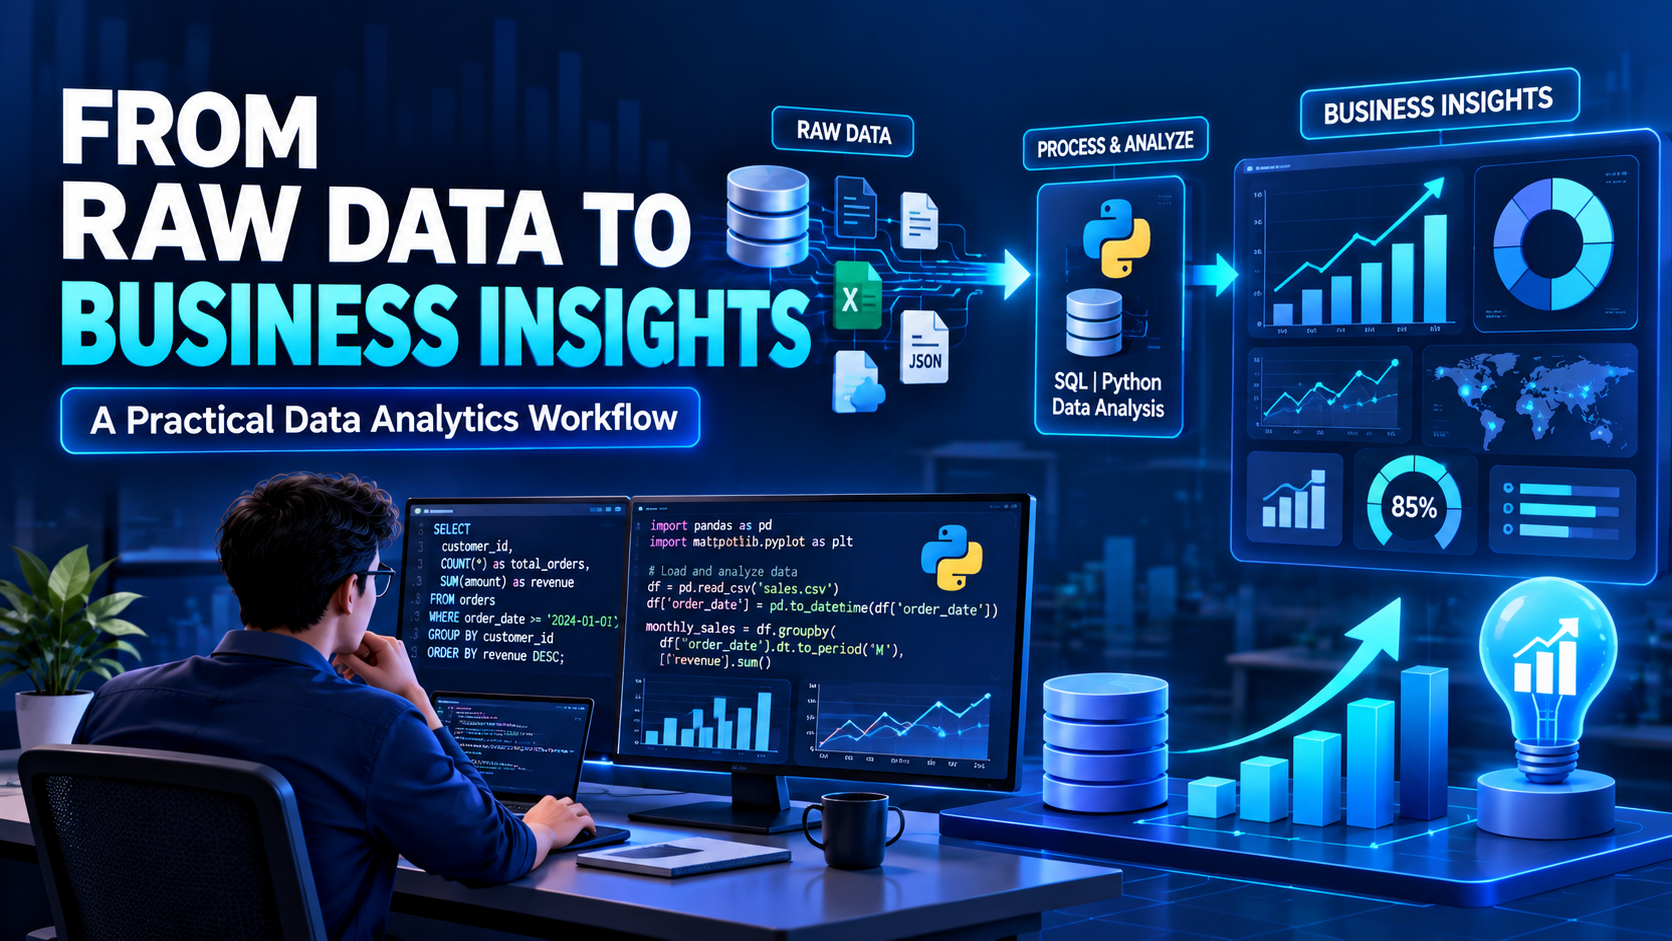
Data Science is often introduced through predictive models, algorithms, and visualizations. A dataset is collected, a model is trained, and its performance is measured. But in practical projects, building a model is only one part of the work.
A model can achieve impressive test results and still fail to provide useful business insights. The data may not represent real operating conditions, the evaluation method may be inappropriate, or the predictions may not help anyone make a better decision.
For aspiring data scientists and professionals developing their analytical skills, understanding these challenges is essential. Reliable Data Science begins with a well-defined problem, trustworthy data, appropriate evaluation, and a clear plan for using the results.
This article explores how to approach Data Science projects with a focus on analytical rigor, practical implementation, and responsible decision-making.
1. Start With the Business Problem, Not the Algorithm
One of the most important steps in a Data Science project happens before writing code: defining the problem.
Imagine an e-commerce company wants to reduce customer churn. A team might immediately start looking for classification algorithms. However, several questions need to be answered first:
What exactly counts as customer churn?
How far in advance should the company identify a customer at risk?
Which customers are included in the analysis?
What information is available at prediction time?
How will the business use the predictions?
Which mistakes are more costly: missing a likely churner or incorrectly flagging a loyal customer?
These questions shape the dataset, target variable, evaluation metrics, and eventual use of the model.
For example, a model that identifies customers who have already stopped purchasing may provide little value if the objective is to intervene before they leave.
A clearly defined problem helps prevent technically correct work from solving the wrong business question.
2. Data Quality Determines What a Model Can Learn
Machine learning algorithms learn patterns from the examples they receive. If those examples contain errors, inconsistencies, or systematic gaps, the resulting model may produce misleading predictions.
Before training a model, investigate the dataset carefully.
Check Missing Values
Missing information may result from incomplete forms, unavailable records, failed integrations, or fields that do not apply to every customer.
Do not automatically replace every missing value with zero. Zero may represent a meaningful measurement rather than an unknown value.
Instead, investigate why values are missing and choose a treatment that fits the data and the problem.
Identify Duplicate and Inconsistent Records
Duplicate transactions, inconsistent product categories, incorrect date formats, and mismatched customer identifiers can distort analysis.
Data cleaning should include checks for these issues, with important transformations documented so that the process can be repeated.
Look for Data Leakage
Data leakage occurs when information unavailable at the intended prediction time influences model training or evaluation.
For example, a churn model could accidentally use a field created only after a customer has cancelled a subscription. The model might appear highly accurate during testing but fail when used to predict future churn.
A useful question to ask is:
Would this information genuinely be available when the prediction needs to be made?
If the answer is no, the feature may introduce leakage.
3. Use Python to Make Data Validation Repeatable
Python is widely used in Data Science because it supports data manipulation, visualization, statistical analysis, and machine learning within a flexible ecosystem.
Libraries such as Pandas and NumPy are useful for inspecting and preparing structured datasets.
Consider a simple example using Pandas:
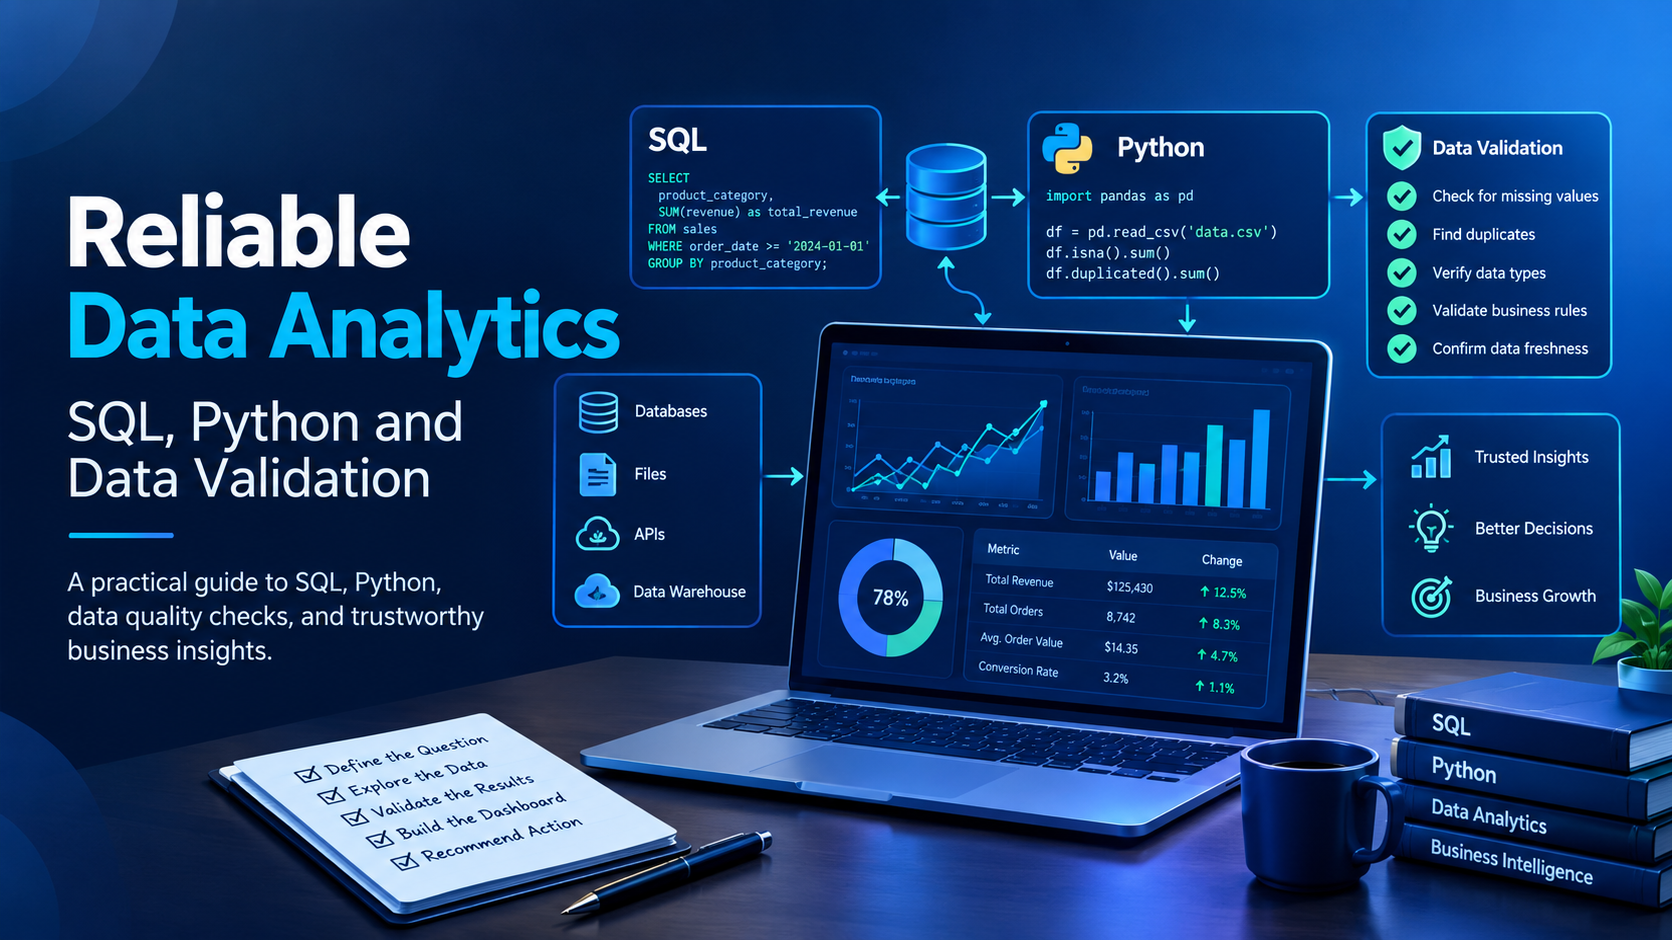
import pandas as pd

df = pd.read_csv("customer_data.csv")

# Inspect the dataset
print(df.shape)
print(df.dtypes)

# Check missing values
missing = df.isna().sum()
print(missing[missing > 0])

# Check duplicate rows
print("Duplicate rows:", df.duplicated().sum())

# Review basic numerical statistics
print(df.describe())
This code provides an initial overview of the dataset. It does not automatically make the data suitable for modeling, but it helps identify areas that require further investigation.
A stronger project can turn important checks into repeatable validation steps. For example, the workflow could flag unexpected missing-value rates, invalid dates, or records that violate business rules.
Repeatable validation is particularly valuable when datasets are refreshed regularly or when multiple people contribute to the same project.
4. Choose an Evaluation Method That Matches the Problem
Model evaluation should reflect the real task rather than focus on a single attractive score.
Suppose a fraud detection dataset contains 99% legitimate transactions and 1% fraudulent transactions. A model that predicts every transaction as legitimate would achieve 99% accuracy while detecting no fraud.
This illustrates why accuracy alone can be misleading for imbalanced classification problems.
Depending on the objective, other metrics may be more informative:
Precision: Of the cases predicted as positive, how many were actually positive?
Recall: Of the actual positive cases, how many did the model identify?
F1-score: What is the harmonic mean of precision and recall?
ROC-AUC: How well does the model rank positive cases above negative cases across classification thresholds?
Mean absolute error (MAE): How large are the average absolute prediction errors in a regression problem?
The appropriate metric depends on the costs of different errors and the intended use of the predictions.
For example, a screening system designed to identify potentially serious cases may prioritize recall, while a workflow with expensive manual reviews may need to consider precision carefully.
Evaluation should also use a suitable validation strategy. Random splits may work for some independent observations, while time-dependent problems often require chronological splits to avoid training on future information.
5. Build a Baseline Before Trying Complex Models
Advanced algorithms are not automatically the best starting point.
A baseline provides a reference against which more sophisticated approaches can be evaluated.
For a classification problem, a baseline might predict the majority class. For a numerical forecasting problem, it could predict the previous period's value or the historical average.
A simple baseline helps answer an important question: Does the new model provide meaningful improvement over a straightforward alternative?
From there, a data scientist can compare suitable approaches, such as logistic regression, decision trees, random forests, or gradient-boosting models.
The comparison should consider more than predictive performance. Training time, inference speed, interpretability, maintenance requirements, and the cost of mistakes may also matter.
A simpler model that meets the business requirement and is easier to maintain can be a better choice than a complex model with only a marginal performance improvement.
6. Translate Predictions Into Decisions
A prediction is not automatically a recommendation, and a recommendation is not automatically a successful business outcome.
Suppose a model identifies customers who may stop purchasing. The next step is to determine how the business should use that information.
Possible actions could include:
Investigating the factors associated with churn
Prioritizing customers for support
Testing targeted retention campaigns
Comparing the cost of interventions with their outcomes
Monitoring whether the interventions actually reduce churn
The model's predictions should be evaluated alongside the resulting decisions.
It is also important to distinguish correlation from causation. If customers who receive a particular offer have higher retention, that does not necessarily mean the offer caused the improvement. Those customers may have differed from other customers in important ways.
Carefully designed experiments, appropriate statistical methods, and domain knowledge can help assess whether an intervention produces a real effect.
7. Treat Deployment as Part of the Data Science Lifecycle
A Data Science project does not necessarily end when the model passes an evaluation.
If the model is used in a live environment, its inputs and the patterns it encounters may change over time. A model trained on historical customer behavior may become less useful when pricing, products, customer preferences, or business processes change.
A practical deployment plan should address several areas.
Reproducibility: Keep track of data preparation, model settings, dependencies, and evaluation results.
Monitoring: Track input quality, prediction behavior, and relevant performance measures.
Versioning: Record which model version generated particular predictions.
Error handling: Define what happens when data is missing, a service is unavailable, or an input falls outside expected limits.
Human oversight: Establish review procedures for decisions that are sensitive, high-impact, or difficult to reverse.
Monitoring matters because a model's performance during development does not guarantee that it will remain suitable in production.
8. Build a Data Science Project That Demonstrates Your Reasoning
A useful portfolio project should demonstrate more than the ability to run a machine learning library.
Consider a customer churn prediction project.
Begin by defining churn and explaining why the organization would want to predict it. Inspect the dataset, document missing values, investigate potential leakage, and conduct exploratory analysis.
Next, establish a baseline, select an appropriate validation strategy, and compare a small number of suitable models. Explain the evaluation metrics and discuss the trade-offs between false positives and false negatives.
Finally, present the findings in a clear report or dashboard. Include limitations, assumptions, and recommendations for further investigation.
A well-documented project should answer five questions:
What problem were you trying to solve?
What data did you use, and what limitations did it have?
How did you prepare and evaluate the data and model?
What did the results actually demonstrate?
How could the findings be used, and what remains uncertain?
This structure demonstrates analytical thinking and responsible interpretation rather than simply displaying a high score.
9. Which Skills Should You Develop for Practical Data Science?
A strong Data Science learning path brings together several complementary skills.
Python: Data manipulation, reusable code, analysis, and automation.
SQL: Retrieving, filtering, joining, and aggregating data from relational databases.
Statistics: Understanding distributions, uncertainty, sampling, correlation, and inference.
Exploratory data analysis: Identifying patterns, anomalies, and relationships before modeling.
Machine learning: Selecting algorithms, establishing baselines, tuning models, and evaluating performance.
Data visualization: Communicating findings clearly and avoiding misleading charts.
Business understanding: Connecting technical outputs with meaningful decisions.
Model deployment and monitoring: Understanding how analytical solutions can be integrated into applications and maintained over time.
If you are building these skills systematically, Data Science Training in India is one curriculum option to review. Compare the syllabus, practical projects, assessment methods, and support available to determine whether the program matches your current level and learning objectives.
The most useful learning experience is one that allows you to apply concepts to realistic datasets, explain your decisions, and learn from mistakes—not simply follow code examples.
10. Common Mistakes to Avoid in Data Science Projects
Even a technically capable learner can weaken a project by overlooking basic analytical principles.
Choosing a model too early: Define the problem, target variable, and evaluation method before selecting algorithms.
Ignoring data quality: Check missing values, duplicates, inconsistent categories, and suspicious records.
Using an unsuitable validation strategy: Ensure the evaluation reflects how the model will encounter new data.
Relying on one metric: Interpret performance in the context of the problem and the cost of errors.
Confusing correlation with causation: A relationship between variables does not prove that one causes the other.
Ignoring limitations: Document assumptions, data gaps, uncertainty, and situations where the model may fail.
Stopping after training: Consider how the results will be communicated, used, monitored, and maintained.
Avoiding these mistakes helps make analytical results more defensible and useful.
Frequently Asked Questions
What is the most important skill in Data Science?
There is no single skill that guarantees success. Problem formulation, data preparation, statistics, programming, model evaluation, and communication all contribute to reliable Data Science work.
Is Python enough to become a data scientist?
Python is highly useful, but it is only one part of the skill set. Data scientists also need statistics, SQL, data preparation, machine learning, evaluation, and an understanding of the problems they are solving.
Why is data cleaning important in machine learning?
Data cleaning helps identify errors, inconsistencies, missing information, and other issues that may distort analysis or model performance. The appropriate treatment depends on the source and meaning of the data.
What is data leakage?
Data leakage occurs when information that should not be available during model training or evaluation influences the model. It can produce overly optimistic results that do not generalize to real-world use.
Is model accuracy enough to evaluate a machine learning model?
No. Accuracy can be misleading, particularly when classes are imbalanced. Depending on the problem, precision, recall, F1-score, ROC-AUC, MAE, or other metrics may provide more relevant information.
What projects should beginners build?
Beginners can start with customer churn analysis, sales forecasting, customer segmentation, fraud detection, or demand prediction. The project should include data validation, a suitable baseline, evaluation, interpretation, and documented limitations.
Why does a Data Science model need monitoring?
Real-world data and operating conditions can change. Monitoring helps identify changes in input quality, model behavior, and predictive performance so that the system can be investigated and updated when necessary.
Final Thoughts
Reliable Data Science is not simply about choosing an algorithm or achieving a high evaluation score. It requires a disciplined process that connects a clearly defined problem with trustworthy data, appropriate validation, meaningful interpretation, and responsible use.
For learners and professionals, the best way to develop these skills is to work through complete projects, document decisions, question assumptions, and explain what the evidence does—and does not—support.